Saturday, 7 November 2015

A Few Tips on Gulp

I have been using Gulp a lot these days and have encountered a few cases that are a bit tricky to solve if you are new to Gulp. These scenarios get even trickier if you used Grunt before and just started using Gulp later, like myself. This is because, Grunt is synchronous and the execution of a Grunt task that combines a set of tasks is predictable. On the other hand, Gulp is asynchronous and we need to carefully examine the way a combined task runs in order to get maximum benefits out of it.

The asynchronous behavior of Gulp tasks makes it a bit difficult to perform things like chaining multiple tasks, handling tasks not returning a stream work seamlessly and performing multiple operations in a single task. In this post, we will see how to handle these tasks.

Chaining Multiple Tasks
It is common to define multiple tasks and combining them to create a master task. The master task alone is called whenever there is a need to perform the set of tasks together. Some of these tasks may be dependent on each other and others may be independent. In general, a set of Gulp tasks are combined using the following syntax:

gulp.task('build', ['copy-files', 'concat-files', 'run-tests', 'copy-coverage-results']);
Out of these tasks, the task concat-files is dependent on the task copy-files. The above setup starts executing these tasks at the same time. Execution of the task concat-files is not paused until execution of the task copy-files is completed. It can be solved in two ways. One way is to declare the task copy-files as a dependent task on the task concat-files and have the concat-files task alone as dependency on the build task.

gulp.task('concat-files', ['copy-files'], function(){
  //definition of the task
});


The second way is to run these tasks in sequence using the run-sequence package. It is shown below:

var runSequence = require('run-sequence');
gulp.task('copy-and-concat', function(){
  return runSequence('copy-files','concat-files');
});


We have to use one of these ways to solve this case based on the scenario in hand.

Task not returning a Stream
Sometimes we have to deal with tasks that don’t return streams. Such tasks are difficult to chain, as gulp doesn’t understand about their completion. One of such tasks is gulp-requirejs. We need to wrap execution of such tasks inside gulp pipes to make them return streams. Following snippet wraps the gulp-requirejs task inside a pipe:


gulp.src('undefined.js')
  .pipe(requires(/*configuration of the task goes here*/))
  .pipe(gulp.dest('path-of-destiation'));


Task handling Multiple Operations
A task may handle multiple asynchronous operations. In such case, the task has to return a stream representing the combined execution. Sometimes, we can return the stream returned by the last operation alone, but this approach doesn’t guarantee that all tasks are completed by the time the stream is completed. So, it is a good practice to combine such tasks using the event-stream package. Following snippet combines a number of copy operations into a single task using this package:

gulp.task('copy-files', function () {
  return es.merge(
    gulp.src('app/index.html')
      .pipe(gulp.dest('build')),
    gulp.src('app/JSON/*.json')
      .pipe(gulp.dest('build/JSON')),
    gulp.src('app/requirejs-config.js')
      .pipe(gulp.dest('build/temp'))
    );
});


I have encountered these cases quite a few times and the solutions discussed here worked well for me. These may not be the only possible ways to tackle these cases, but these are just my views. If you got any other ways to solve these problems, feel free to add a comment.

Happy coding!

Saturday, 10 October 2015

Book Review - AngularJS by Example

I have just finished reading the book AngularJS by Example authored by Chandermani Arora. I will share my views on this book in this post.

A typical technology book starts with concepts on the technology and it continues to explain the technology throughout the book with independent examples. This book takes a different approach and start building an application right from beginning of the book. It continues adding features to the same example while explaining different concepts of the framework and covering internal details wherever needed.

Presentation of the entire book can be summarized into following the bullet points:

  • Starts with a brief discussion on problems with building large JavaScript applications. Explains need of patterns like MVC in the ecosystem
  • Doesn't build a regular "Hello World" sample, instead builds an interesting sample to cover basic constructs of the framework
  • Before building any step of the sample, the author spends time in explaining the problem, then tells which feature solves the problem and then explains the feature thoroughly before implementing the next step
  • Covers a number of tips through examples
  • Makes good use of the notes section to clarify some basics and lesser known facts
  • No concept is explained independently. Most of the necessary features of the framework are covered with right examples that are very close to real world problems
  • I particularly like the way some features like animations, ng-model, interceptors and testing are explained in the book
  • Last chapter focuses on a few common scenarios and provides advice containing best practices to solve these problems


This book doesn't just helps someone in gaining knowledge on AngularJS, but also teaches the needs of the features. Once you finish reading the book by following along with it and build the sample, you will have a self-built reference application that you can refer in the future.

The content in this book is relevant to both beginners and experienced developers working on AngularJS. A thorough read of this book will help you in mastering essential parts of the framework. You will also be able to answer most of the common interview questions once you read this book :).

Happy coding!

Friday, 25 September 2015

Writing Gulpfile using TypeScript

Lately, I have been using Gulp a lot at my work and also in the demos of my articles. I also use TypeScript quite often these days while playing with Angular 2. While using Gulp to transpile TypeScript to JavaScript using Gulp, I got thought to use TypeScript itself to write the gulpfile as well. It might sound a bit weird as we use Gulp to transpile the files to JavaScript and the gulpfile itself has to be converted by someone into JavaScript before any other task runs. Thanks to npm scripts, we have a way to achieve this.

The scripts section of the package.json file can be used to register commands and these commands can be executed from command prompt of any OS using the “npm run” command. For instance, if we have the following configuration saved in scripts section of package.json file:

"scripts": {
  "setup" : "npm install && bower install"
}

We can run the command “npm run setup” from the command prompt. This command would install all Node.js dependencies and the bower dependencies. We can transpile the gulpfile using this section and then combine this command with a command to run a task. For this, we need to have TypeScript installed globally. This can be done using the following command:

> npm install –g typescript

To write the gulpfile using TypeScript and take advantage of the type checking system, we need to get the type definition files. Type definitions for the gulpfile are available on tsd. Following command gets the type definitions for the gulpfile:

> tsd install gulp --save

These files are saved inside typings folder of the project. To make our lives easier, the tsd command creates a type definition file that refers to all of the installed type definitions. This file is tsd.d.ts inside the typings folder.

Now, we need to refer the tsd.d.ts file in the gulpfile.ts file and start writing Gulp tasks. Following snippet shows a task that concatenates all JavaScript files:

/// <reference path="typings/tsd.d.ts" />

var gulp = require('gulp'),
    concat = require('gulp-concat');

gulp.task('default', function(){
  return gulp.src(["scripts/*.js"])
    .pipe(concat("combined.js"))
    .pipe(gulp.dest("dist"));
});

This example is a simple one. In more advanced scenarios, we can use types as well.

To run this gulp task, we need to define a command in the scripts section to transpile the file and then run the task. Following is the command:

"scripts": {
  "concat": "tsc gulpfile.ts && gulp"
}

All is done. We can now run this command as follows:

> npm run concat

Happy coding!

Tuesday, 30 June 2015

Debugging and Profiling LINQ Queries using Devart LINQ Insight

Language Integrated Query (LINQ) is one of the features that makes .NET developers happy. LINQ opened up the opportunities to uniformly query in-memory objects, data in relational DBs, OData Services and many other data sources. Writing LINQ queries is fun as they reduce the usage of loops in code and keep the code base simple.

There are several ways to write LINQ queries to obtain a given result. As programmers, it is our responsibility to find the best way out of them and use that to make the applications perform better. Also, LINQ queries are hard to debug. It is not possible to debug a LINQ query using immediate window of Visual Studio debugging tools. So, we can’t say if a LINQ query is completely correct unless we write enough unit tests around it. Though unit tests are a good way to verify, nothing beats the ability of debugging the query by changing parameters.

LINQ Insight is a Visual Studio extension from Devart that makes debugging and profiling LINQ queries easier. It also provides profiling data for the LINQ queries and for CRUD operations performed using LINQ to in-memory objects as well as LINQ to remote objects (LINQ to SQL, Entity Framework, NHibernate and others). In this post, we will see a few of the features of this tool.

Debugging LINQ Queries
Once you installed LINQ Insight and restarted Visual Studio, you will see the options to see LINQ Interactive and LINQ Profiler windows under the View menu:


To debug the queries, we need to view the LINQ Interactive window. Select this option to view the window. Say, I have the following generic list of Persons in my application:
var people = new List<Person>() {
    new Person(){Id=1, Name="Ravi", Occupation="Software Professional", City="Hyderabad", Gender='M'},
    new Person(){Id=2, Name="Krishna", Occupation="Student", City="Bangalore", Gender='M'},
    new Person(){Id=3, Name="Suchitra", Occupation="Self Employed", City="Delhi", Gender='F'},
    new Person(){Id=4, Name="Kamesh", Occupation="Business", City="Kolkata", Gender='M'},
    new Person(){Id=5, Name="Rani", Occupation="Govt Employee", City="Hyderabad", Gender='F'}
};

Let’s write a LINQ query to fetch all males or, females from this list using a character parameter. Following is the query:
var gender = 'M';

var males = people.Where(p => p.Gender == gender).Select(p => new { Name=p.Name, Occupation=p.Occupation });

Right click on the query and choose the option “Run LINQ Query”. You will see this query in the LINQ Interactive window and its corresponding results.


As the query accepts a parameter, we can change value of the parameter and test behavior of the query. Hit the Edit Parameters button in the LINQ Interactive window and modify value of the parameters used in the query. On clicking OK, the query is executed and the result is refreshed.

Profiling Calls to Entity Framework
As most of you know, ORMs like Entity Framework convert LINQ Queries and function calls into SQL Queries and statements. The same result can be obtained using different types of queries. It is our responsibility to measure the execution time of all possible approaches of writing a query and choose the best one out of them.

For example, consider a database with two tables: Student and Marks.


The need is to find details of a student and the marks obtained by the student. It can be achieved in two ways. The first way is to find sum of the marks using navigation property on the student object and the other is to query the Marks DbSet using group by clause:
var studMarks1 = context.Students.Where(s => s.StudentId == studentid)
                        .Select(s => new
                        {
                            Name = s.Name,
                            Id = s.StudentId,
                            City = s.City,
                            TotalMarks = s.Marks.Sum(m => m.MarksAwarded),
                            OutOf = s.Marks.Sum(m => m.MaxMarks)
                        });

var studMarks2 = context.Marks.Where(m => m.StudentId == studentid)
                         .GroupBy(sm => sm.StudentId)
                         .Select(marksGroup => new
                         {
                             Name = marksGroup.FirstOrDefault().Student.Name,
                             Id = marksGroup.FirstOrDefault().Student.StudentId,
                             City = marksGroup.FirstOrDefault().Student.City,
                             TotalMarks = marksGroup.Sum(m => m.MarksAwarded),
                             OutOf = marksGroup.Sum(m => m.MarksAwarded)
                         });

Let’s see how much time does each of the above query takes using LINQ Profiler. Go to View menu and choose option to see the LINQ Profiler window. Now debug the application. After both of the queries are executed, visit the profiler window. You will see the data collected by the profiler. Following screenshot shows an instance of profiler’s data after running the above queries:

You can observe how much time each of these queries takes in different instances and with different values of the parameters before concluding that one of them is better than the other one.

As we saw, LINQ Insight adds a value add to the .NET developers. Devart has a number of other tools to help developers as well. Make sure to check them out and use them to make your development experience more enjoyable!

Happy coding!

Saturday, 13 June 2015

Everything You Need to Know to Unit Test AngularJS Code

Unit testing is one of the crucial and necessary parts of software development. This phase improves the quality of product, assures accuracy in behavior and also reduces the cost involved in fixing the bugs. There are some good advantages for a developer writing unit tests as well.

AngularJS is one of the most popular framework for building Single Page Applications. One of the key reasons behind its success is, testability. Every piece of code written in AngularJS is unit testable. The features like Dependency Injection make the code written on the framework easier to test.

In the past, I wrote a few posts on unit testing AngularJS controller using Jasmine and QUnit and I also covered a few tips. Over past two years, I worked a lot on AngularJS and thus I wrote a lot of code and tests. This process taught me a lot of tips on unit testing AngularJS code that I wanted to share with the community. As some of you might be aware that I am a regular author for SitePoint, I have put together a series of four articles covering tips on mocking and testing almost every block in AngularJS. Following are the links to these articles:


  1. Mocking Dependencies in AngularJS Tests
  2. Unit Testing in AngularJS: Services, Controllers & Providers
  3. AngularJS Testing Tips: Testing Directives
  4. AngularJS Testing: Bootstrap Blocks, Routes, Events, and Animations


The process of putting these articles together has not been easy for me and at the same time, I enjoyed a lot while writing them. Read them when you get time and feel free to drop any feedback to me.

Happy coding!

Sunday, 26 April 2015

Getting Started with Benchpress

Lately, most of us are quite busy with writing great front-end centric applications to make the look and feeling of our apps jazzy. Despite of the jazziness, the application won’t give a great experience to the user unless it performs really well on the browser. Performance of any piece of code can be improved only if we know that there is some scope for the improvement. Benchpress is one of the tools available to measure performance of AngularJS applications. In this post, we will see how to install benchpress and get started with using the data it provides us.

Benchpress is a performance measuring tool built on top of Protractor. It is built by the Angular team and is extensively used by them to measure performance of the framework. It is made available and can be used by anyone to measure performance of the Angular apps.

Installing Benchpress

Benchpress is an NPM package. So, it needs Node.js to be installed. As it uses protractor, you need to install protractor globally. Use the following command to install protractor:

npm install –g protractor

If you are installing it on a Windows machine, webdriver-manager may throw an error. To oversome this, you will have to update the webdriver-manager. Following command updates it:

webdriver-manager update

Restart the command prompt after this command completes execution.
Install protractor again after updating the webdriver-manager and it shouldn’t fail this time. You can find more details on installing protractor in its official documentation on GitHub.
Now that the system has protractor available as a global package, we can install benchpress. Benchpress also has to be installed globally. Following is the command:

npm install -g generator-benchpress

Getting a Glimpse of Benchpress ng-tasty
Now that we have all of the required setup, we can apply benchpress on a project. For this post, I will show the benchpress results using the yeoman scaffold of ng-tasty. I will explain the process of getting benchpress results on an existing piece of code in a future article. As we need to install a yeoman scaffold, you must have yeoman installed. If you don’t already have, run the following command to install it:

npm install –g yo

Create a new folder at your desired location and install the following NPM packages locally:
  • http-server
  • benchpress


Benchpress needs these packages to start the Node.js HTTP server and run the scenarios tests. The final thing that we need to get is, the yeoman scaffold. Run the following command in the same folder where the above NPM packages are installed: yo benchpress ng-tasty

This scaffold adds a folder called benchmarks and inside this folder and the folder has following content:
  • protractorBenchmarks.conf.js: It is the configuration file for benchpress. It contains the browser details, spec files to run, test framework to use, the task to be performed before launching benchpress and a config object for jasmine
  • index.html: This file is inside the ng-tasty folder and it is the page to be inspected on
  • benchmark.spec.js: This file is inside the ng-tasty folder. The spec file that uses Selenium web driver to perform operations on the page
Now, we have everything to run benchpress and see some results. Run the following command on the console and see the outcome:

protractor benchmarks\protractorBenchmarks.conf.js

This command starts Selenium Web Driver and loads the index.html on Chrome. It performs the set of operations configured and prints results on the console.


Happy coding!

Wednesday, 7 January 2015

Private Members in ES6 Classes

Classes in ECMAScript 6 are easy to write and use. Yet, they have certain limitations. One of them is, there is no direct way to create a private member inside the class.

The classes don’t allow us to declare variables directly inside body of the class. All members defined/declared inside the class or attached to an instance using this keyword are directly available to the instance of the class.

When I Googled it, I found a few posts on it and answers suggesting to use Symbol. I think, Symbol was private sometime back but according to the current draft of ES6, properties created using Symbol values are not private anymore. Though value of Symbol can't be reproducible, one can read Symbol properties using Object.getOwnPropertySymbols.

For example, consider the following class and object:


const ID = Symbol();
class Employee{
  constructor(id, name){
    this.name = name;
    this[ID] = id;
  }
}
var emp = new Employee(1001, "Ravi");


Though value of id is not accessible using emp[Symbol()], as it returns a different Symbol, we can extract all Symbols used for properties and values of these properties as:

var symbolsInEmp = Object.getOwnPropertySymbols(emp);
symbolsInEmp.forEach(function(symbol){
  console.log(emp[symbol]);
});


The above snippet will print value of id stored in the object emp. If there are multiple Symbol properties, you may not be able to find which value corresponds to what value, but the data is not private.

To make a value private, we can do one of the following:

  • set and use the value inside a closure
  • create the variable inside a module and not export it


WeakMap seems to be a good option for creating the private fields. Because, it accepts any value as key and it doesn’t prevent the key object from getting garbage collected when the WeakMap object still exists. It removes entry containing the object once it is garbage collected. For each private field, we need to create a new WeakMap object.

Following snippet shows how WeakMaps can be used as private fields:


const ID = new WeakMap();
const PAN = new WeakMap();

class Employee{
  constructor(id, name, pan){
    this.name = name;
    ID.set(this, id);
    PAN.set(this, pan);
  }
  getPan(){
    return PAN.get(this);
  }
}
var emp = new Employee(1001, "Ravi", "FFHH1919JJ");
console.log(emp.getPan());

export default Employee;


As you see, we are exporting the Employee class alone from the module. Here, the classes don't contain the fields themselves, but they are relying on the private objects of the module to keep the data private.

Happy Coding!

Thursday, 1 January 2015

Static Class Members in ES6

I have been playing with ECMAScript 6 for some time now and I must say that the new features added in this edition are worth taking a look. One of the significant language feature added in this specification is, support for classes. If you are not aware of the features of ES6, checkout the specification on official site for ECMA Script or, the un-official HTML version of the specification on Mozilla’s site.

ES6 classes support most of the features like creating object, constructor, inheritance and overriding that are supported by Object Oriented programming languages like C# or Java. And because it is JavaScript, there is no static type checking.

I found it interesting when I saw the support for static members in the specification. The specification says, we can add a static method to a class using the following syntax:


static methodName(){
}


But, if you attempt to declare a static property as follows:

static propertyName;


It results in an error. So, we can’t declare a static property. But, we can create it inside a method and use it. To access a static member inside a static method, we need to use this keyword. Because, this reference in JavaScript refers to the object using which the method is invoked. Static methods are called using name of the class to which they belong and name of the class in JavaScript refers an object that has a prototype property containing instance members of the class. For example, consider the following class:

class Employee
{
  constructor(){
    this.name = "Ravi";
  }
  setName(name){
    this.name = name;
  }
}


The above code is similar to:

function Employee(){
  this.name="Ravi";
}
Employee.prototype = {
  setName: function(name){
    this.name=name;
  }
};


Here Employee is name of the class and at the same time, it is also an object. All static members of the Employee class are attached to the Employee object.

Let’s add a static method to the Employee class:


class Employee
{
  constructor(){
    this.name = "Ravi";
  }
  setName(name){
    this.name = name;
  }

  static getCounter(){
    if(!this.counter && this.counter!==0){
      this.counter=0;
    }
    else{
      this.counter++;
    }
    return this.counter;
  }
}


The property counter used in the getCounter method of the above snippet becomes a static property, as it is assigned to this reference inside a static method. Similarly, another static method of the class can be called from a static method using this reference.

The following console.log statements will print the results specified in the comments:


console.log(Employee.getCounter());  //0
console.log(Employee.counter);       //0
console.log(Employee.getCounter());  //1
console.log(Employee.counter);       //1
console.log(Employee.getCounter());  //2
console.log(Employee.counter);       //2


Happy Coding!

Thursday, 25 December 2014

Automating Tasks in Front-end Web Apps Using Gulp

As we started writing a lot of JavaScript and CSS these days, front-end development has matured like anything. We create hundreds of JavaScript source files to make our code organized; but finally we need to ship just one JavaScript file and one CSS file while deploying the application. This conversion is not easy; as it involves several steps like running tests, validating against jshint, concatenating, minifying, uglifying and many other tasks. Thankfully, we have a number of automated task runners and a handful of plugins on each of these task runners to make these tasks easier.

Out of the existing task runners, Grunt and Gulp are most widely used. I use Grunt a lot these days. Though I haven’t blogged about it, I used it in some of my SitePoint articles. Lately, Gulp is becoming more famous. Gulp uses a different approach to address the same problem that Grunt addresses. Let’s see how we can leverage Gulp to automate our tasks.

Gulp is a task runner based on Node.js. It uses streams to carry its tasks. The way Gulp works is, it accepts a source (can be a file, or a set of files), processes them based on a task and passes it to the next task in the pipe for further processing. The pipes continues processing till the last task. Following is the syntax of a typical Gulp task:

gulp.task('task-name', function () {
  return gulp.src([source paths])
    .pipe(task1(parameters))
    .pipe(task2())
    ...
    ...
    ...
    .pipe(taskn())
    .pipe(gulp.dest('destination-path'));
});

Tasks piped in the above Gulp task are tasks loaded using Gulp plugins. Gulp has a huge number of plugins contributed and actively developed by community, which makes it a very good ecosystem. To be able to use Gulp in your project, you need to have it installed globally and locally. Run the following commands in a command prompt to get Gulp installed:

  • npm installed –g gulp
  • npm installed gulp --save-dev (To be ran in your project folder)


Let’s write a Gulp task for cleaning distribution files and regenerating them after concatenating and minifying. For this, we need the following Gulp plugins:

  • gulp-clean
  • gulp-concat
  • gulp-uglify


These can be installed using the following nom commands:
  • npm install gulp-clean --save-dev
  • npm install gulp-concat --save-dev
  • npm install gulp-uglify --save-dev


Add a file to the project and rename it to Gulpfile.js. Load the Gulp tasks in this file:


var gulp = require('gulp'),
    concat = require('gulp-concat'),
    uglify = require('gulp-uglify'),
    clean = require('gulp-clean');


Before generating the files to be deployed, let’s clean the folder. Following task does this:

gulp.task('clean', function () {
    return gulp.src(['dist'])
        .pipe(clean());
});


Now, let’s create a bundle task that concatenates all JS files, uglifies them and copies inside a folder to be distributed. Following is the task:

gulp.task('bundle', function () {
  return gulp.src(['public/src/*.js'])
    .pipe(concat('dist/combined.js'))
    .pipe(uglify())
    .pipe(gulp.dest('.'));
});


The folder public/src contains all JS files of the application. They are concatenated into one file and the contents are then uglified and finally we call the dest task to copy the resultant file to destination, which is the dist folder.

These two tasks can be combined into one task as follows:


gulp.task('createDist', ['clean', 'bundle']);


Now, if you run the following command, you will have the combined.js file created inside dist folder.

gulp createDist

To make a task default, name of the task has to be default.


gulp.task('default', ['clean', 'bundle']);


To run this task, you can run gulp command without passing names of any tasks to it.

We will see explore more features of Gulp in future posts.

Happy coding!

Monday, 27 October 2014

Form Validation and Displaying Error Messages using ngMessages in AngularJS 1.3

AngularJS 1.3 was released around two weeks back. As the core Angular team says, it is the best AngularJS released till date. It comes with a bunch of new features and performance improvements.

One of the key changes in this release is the changes made to forms. The directives form and ngModel went through a number of changes to make it easier to perform validation. The framework has a new module, ngMessages that makes the job of displaying validation messages easier.

In the current release, FormController have following additional APIs:

  • $setUntouched(): A method that sets all controls in the form to untouched. It is good to call this method along with $setPristine()
  • $setSubmitted(): A method that sets the state of the form to submitted
  • $submitted: A boolean property that indicates if the form is submitted

NgModelController has the following additional APIs:

  • $setUntouched(): A method that sets the control to untouched state
  • $setTouched(): A method that sets the control to touched state
  • $validators: A list of synchronous validators that are executed when $validate method is called
  • $asyncValidators: A list of asynchronous validators that are executed when $validate method is called
  • $validate(): A method that executes all validators applied on the control. It calls all synchronous validators followed by asynchronous validators
  • $touched: Boolean property that indicates if the control is touched. It is automatically set to true as soon as cursor moves into the control
  • $untouched: Boolean property that indicates if the control is untouched

For more details on these APIs, read the official API documentation of FormController and NgModelController.

Let’s see these APIs and the new featured in action. Consider the following form:


<form name='vm.inputForm' ng-submit='vm.saveNewItem()' novalidate>
  Item Name: <input name='itemName' type="text" ng-model='vm.newItem.name' required non-existing-name />
  <br />
  Min Price: <input name='minPrice' type="text" ng-model='vm.newItem.minPrice' required ng-pattern='vm.numberPattern' />
  <br />
  Max Price: <input name='maxPrice' type="text" ng-model='vm.newItem.maxPrice' required ng-pattern='vm.numberPattern' greater-than='vm.newItem.minPrice' />
  <br />
  Quantity Arrived: <input name='quantity' type="text" ng-model='vm.newItem.quantity' ng-pattern='vm.numberPattern' />
  <br />

  <input type="submit" value="Save Item" />
</form>

Note: Notice name of the form in the above snippet. It is not the way we usually name the HTML elements. We assigned a property of an object instead of a plain string name. Reason for using this is to make the form available in the controller instance. This approach is very useful in case of controllerAs syntax. (Credits: Josh Caroll’s blog post)

The form has some built-in validation and two custom validations. Built-in validations work the same way as they used to in the earlier versions ( Refer to my old blog post that talks a lot about the validations). We will write the custom validations in a minute.

Following is the controller of the page. As stated above, I am using “controller as” syntax, so no $scope in the controller.


var app = angular.module('formDemoApp', ['ngMessages']);

app.controller('SampleCtrl', function(){
  var vm = this;

  vm.inputForm = {};

  vm.numberPattern = /^\d*$/;

  vm.saveNewItem = function(){
    vm.newItem={};
    vm.inputForm.$setPristine();
    vm.inputForm.$setUntouched();
  };
});

Custom Synchronous Validations

The process of defining custom validations has been simplified in AngularJS 1.3 with $validators and $asyncValidators. We don’t need to deal anymore with $setValidity() to set validity of the control.

In case of synchronous validations, we need to return a boolean value from the validator function. The validation is passed when result of the validator function is true; otherwise, it fails.

In the form, we are accepting min price and max price values. The form should validate that the value of min price is always less than value of max price. Following is the directive for this validation:


app.directive('greaterThan', function(){
  return {
    restrict:'A',
    scope:{
      greaterThanNumber:'=greaterThan'
    },
    require: 'ngModel',
    link: function(scope, elem, attrs, ngModelCtrl){
      ngModelCtrl.$validators.greaterThan= function(value){
          return parseInt(value) >= parseInt(scope.greaterThanNumber);
      };

      scope.$watch('greaterThanNumber', function(){
        ngModelCtrl.$validate();
      });
    }
  };
});

If the above validation fails, it sets invalid flag to greaterThan validation on the control. Name of the method set to $validators is used as the validator string.

Custom Asynchronous Validations

In some scenarios, we may have to query a REST API to check for validity of data. As AJAX calls happen asynchronously, the validator function has to deal with promises to perform the task.

For the demo, I created a dummy asynchronous method inside a factory that checks for existence of the new item name in a static array and resolves a promise with a boolean value. Following is the service:


app.factory('itemsDataSvc', ['$q',function($q){
  var itemNames=['Soap', 'Shampoo', 'Perfume', 'Nail Cutter'];

  var factory={};

  factory.itemNameExists=function(name){
    var nameExists = false;
    itemNames.forEach(function(itemName){
      if(itemName === name){
        nameExists=true;
      }
    });
    return $q.when(nameExists);
  };

  return factory;
}]);

The difference between synchronous and asynchronous validators is the API used to resister the validator and the return value of the validator method. As already stated, $asyncValidators of NgModelController is used to register the validator and the validator method has to return a promise. The validation passes when promise is resolved and the validation fails if the promise is rejected.

Following is the custom asynchronous validator that checks for unique name:


app.directive('nonExistingName', ['itemsDataSvc','$q',function(itemsDataSvc, $q){
  return {
    restrict:'A',
    require:'ngModel',
    link: function(scope, elem, attrs, ngModelCtrl){
      ngModelCtrl.$asyncValidators.nonExistingName = function(value){
        var deferred = $q.defer();

        itemsDataSvc.itemNameExists(value).then(function(result){
          if(result){
            deferred.reject();
          }
          else{
            deferred.resolve();
          }
        });

        return deferred.promise;
      };
    }
  };
}]);

Validation Error Messages using ngMessages

Displaying validation messages of the form in AngularJS had not been too good earlier. It used to take a lot of mark-up and conditions to make them look user-friendly. AngularJS 1.3 has a new module, ngMessages that simplifies this task. If you refer to the module definition statement in the controller script, it has a dependency on ngMessages module. This module doesn’t come by default as part of the core framework, we have a separate file for this module.

The ngMessage module contains two directives that help in showing messages:

  • ngMessages: Shows or hides messages out of a list of messages
  • ngMessage: Shows or hides a single message

The directives in ngMessages module support animations as well. I will cover that in a future post.

In case of displaying form validation messages, ngMessages is set to the $error property of the form object and every occurrence of ngMessage element is set to the condition for which the message is has to be displayed.


<div ng-if='vm.inputForm.$dirty &amp;&amp; vm.inputForm.$invalid' ng-messages='vm.inputForm.$error' class='error-messages'>
  <div ng-message='required'>One/more mandatory fields are missing values</div>
  <div ng-message='pattern'>Data is in incorrect format</div>
  <div ng-message='greaterThan'>Invalid range</div>
  <div ng-message='nonExistingName'>Name already exists</div>
</div>

By default, ngMessages displays the first message out of the list even if more than one message is relevant. It can b overridden using multiple or ng-messages-multiple attribute on the ngMessages directive.

The above message list is generic to the form; the messages are not specific to any of the control in the form. To display messages specific to form, you can use the $error property on the form element.


<div ng-if='vm.inputForm.itemName.$dirty' ng-messages='vm.inputForm.itemName.$error' class='error-messages'>
  <div ng-message='required'>One/more mandatory fields are missing values</div>
  <div ng-message='nonExistingName'>Name already exists</div>
</div>

You can play with the sample on Plnkr.

Happy coding!

Sunday, 28 September 2014

Unit Testing Config and Run Blocks in AngularJS

One of the best-selling points of AngularJS framework is testability. Any piece of code written in an AngularJS application is testable unless it is corrupted by a global object.

All of the blocks in AngularJS except config and run blocks can be instantiated or invoked and tested. Config and run blocks are executed as soon as the module containing the block is loaded into memory. There is no way to call them manually; unless the bodies of these blocks are defined independently and then hooked to a module. But, they are invoked automatically when the module is loaded. So, I don’t see a need to invoke them manually to test their logic.

Say, we have the following module with a config block registering routes and a run block that listens to a global message event to the window:


var app = angular.module('testApp',['ngRoute']);

app.config(function($routeProvider){
  $routeProvider.when('/', {templateUrl:'templates/home.html',controller:'homeCtrl'})
    //definitions of other routes
    .otherwise({redirectTo:'/'});
});

app.run(function($window, $rootScope){
  $window.addEventListener('message', function(event){
    $rootScope.$broadcast(event.data);
  });
});


In test of the config block, we need to see if the methods when and otherwise are called with right parameters. To do that, we must spy these methods and store a reference of $routeProvider as soon as the module in loaded in tests. Providers cannot be mocked using $provide like services as they are not available after config phase. We can pass a callback to module loader and create spies on the methods whose calls have to be inspected.

Following snippet shows how to spy on a provider’s method and a test that checks if the method is called:


describe('testing config block', function() {
  var mockRouteProvider;

  beforeEach(function () {
    module('ngRoute', function ($routeProvider) {
      mockRouteProvider = $routeProvider;
      spyOn(mockRouteProvider, 'when').andCallThrough();
      spyOn(mockRouteProvider, 'otherwise').andCallThrough();
    });
    module('testApp');
  });

  it('should have registered a route for \'/\'', function(){
    expect(mockRouteProvider.when).toHaveBeenCalled();
  });
});


If you run the above test now, it should fail. That’s strange, isn’t it?

I spent a lot of time struggling with it and found two approaches to make the above test pass.

One approach is to have a dummy test before the test that performs an assertion on the logic of config block. You can leave this test empty as it doesn’t have to do anything, or have an assertion that would always pass.


it('doesn\'t have any assertions', function(){});


I didn’t like this approach; as it adds a test that would always pass and doesn’t carry any value. The other approach to make the above test pass is by calling inject() inside a beforeEach block. The inject function is generally used to get references of services that are needed in the tests. Even if there is no need of any service in the tests, the inject block can be called without any callback to bootstrap the modules already loaded using module() blocks.

beforeEach(function(){
  inject();
});


You will see the same issue with run() block as well. It isn’t executed unless a test is executed or inject block is executed.

If you got a better approach to bootstrap modules in tests, feel free to post a comment.

Happy coding!

Saturday, 6 September 2014

Serializing and De-serializing JSON data Using ServiceStack

ServiceStack is a light-weight, complete and independent open source web framework for .NET. I recently started playing with it and I must say that it is an awesome framework. It has several nice features including .NET’s fastest JSON serializer.

Each piece in ServiceStack can be used independently. So is its piece for serialization. The serialization package of ServiceStack can be installed via NuGet using the following command:


The above package can be installed on any type of application. Let’s use the following Person class for creating object to serialize/de-serialize:

public class Person
{
    public int Id { get; set; }
    public string Name { get; set; }
    public string City { get; set; }
    public string Occupation { get; set; }
}


Following is a sample object of the person class:

var person = new Person()
{
    Id = 1,
    Name = "Ravi",
    City = "Hyderabad",
    Occupation = "Software Engineer"
};


To serialize this object to a JSON string, we need to use the ServiceStack.Text.JsonSerializer class. Following statement serializes the above object:

var serialized = JsonSerializer.SerializeToString(person);


The above string can be de-serialized using the following statement:

var converted = JsonSerializer.DeserializeFromString<Person>(serialized);


The JsonSerializer class also has APIs to serialize into or de-serialize from TextWriter or Stream.

The APIs in ServiceStack are light-weight and easy to use. I am working on a series of articles on this great framework. Stay tuned for updates.

Happy coding!

Friday, 27 June 2014

Using Promises in NodeJS Apps

To separate logic of accessing data from the routes, we create separate modules to handle the task of data access. When I started learning Node.js, a common pattern that I saw in some samples to separate the data access logic from routing was as follows:

//Route
app.get(‘/api/students’, getAllStudents);

//In data access file
exports.getStudents = function(request, response){
  mongoDbObj.students.find().toArray(function(err, data){
    if(err){
      console.log(err); 
      response.send(500,{error: err});
    }
    else{
      console.log(data);
      response.send(data);
    }
  });
};


Though this approach separates the logic, we are dealing with request and response inside the data access logic. I am personally not a fan of this approach. But, we cannot return the data or error from the above function as we will get them asynchronously. This is where I started thinking of using promises to refactor the above function.

We have several promise libraries available for Node.js. These days, I am playing with Bluebird. It can be installed using npm.

One of the nice features that bluebird provides is, promisifying existing methods. To turn operations defined by an object into asynchronous, we need to pass the object inside the promisifyAll() method.


var Promise=require('bluebird');
var mongodb=Promise.promisifyAll(require('mongodb')); 


The above snippet creates asynchronous versions of each of the function created inside the object mongodb. Let’s convert some of the snippets from my previous post to use async. Code for establishing a connection to MongoDB changes to:

mongoClient.connectAsync('mongodb://localhost/studentsDb')    
           .then(function(db){
              console.log("Connected to MongoDB");
              mongoDbObj={
                db:db,
                students:  db.collection('students')
              };
            }, function(error){
                console.log(error);
            });


Let’s fetch details of all students and return the results asynchronously to the caller. On the result of calling find() method, we need to call the asynchronous method toArray() to convert data from documents to array. It makes sense to return a promise in such scenario as we can’t say when the result will be available. Following is the snippet for fetching data that returns a promise:

exports.getAllStudentsAsync=function(){
  return new Promise(function(resolve, reject){
    mongoDbObj.students.find()
              .toArray(function(err, result){
                 if(err)
                 {
                   reject(err);
                 }
                 else{
                   resolve(result);
                 }
            });
    });
};


Finally, the REST API that sends the student data to the browser changes to:

app.get('/api/students, function(request, response){
  mongoOps.getAllStudentsAsync()
          .then(function(data){
            response.send(data);
          }, function(err){
            response.send(500,{error: err});
          });
});


To me, this seems to be a cleaner approach as the request and response are sent to the model for manipulation. Feel free to express your opinions in the comments.

Happy coding!

Monday, 23 June 2014

Performing CRUD Operations on MongoDB in Node.js Application Using mongodb Driver

A NoSQL database is the go-to choice while writing applications using Node.js. In particular, MongoDB has got a lot of popularity in the community. Thanks to the awesome MEAN (MongoDB-Express-Angular-Node) stack, that makes everyone realize that an entire web app can be written using just one language (JavaScript).

There are a number of drivers created by the community to interact with MongoDB from a Node.js app. The official mongodb driver seems to be the simplest of them. Because, the JavaScript API it provides to interact with MongoDB is quite similar to the way one talks to MongoDB from console. In this post, we will learn to perform simple CRUD operations on a MongoDB document store using the mongodb driver.

We will be dealing with a set of students that is initially loaded with the following data:


{
 "studentId" : 1,
 "class" : 8, 
 "name" : "Ravi", 
 "marks" : [
  { "totalMarks" : 500, "percent" : 83.3 },
  { "totalMarks" : 510, "percent" : 85 } ], 
},
{ 
 "studentId" : 2,
 "name" : "Rupa", 
 "class" : 8, 
 "marks" : [
  { "totalMarks" : 570, "percent" : 95 },
  { "totalMarks" : 576, "percent" : 96 } ] 
}


To be able to work with the above data, we need to establish a connection with MongoDB first. Before that, we need to get the driver installed in the current project. Following command will install the driver when it is ran in the folder where the target Node.js project is located:

npm install mongodb

I prefer placing the code interacting with MongoDB in a separate file. As first thing, we need to get a reference to the MongoDB client and establish a connection:


var mongoClient=require('mongodb').MongoClient;
var mongoDbObj;

mongoClient.connect('mongodb://localhost/studentDb', function(err, db){
  if(err)
    console.log(err);
  else{
    console.log("Connected to MongoDB");
    mongoDbObj={db: db,
      students: db.collection('students')
    };
}


Retrieving values:

In the above connection URL, studentDb is name of the database. If the database doesn’t already exists, it is created automatically. I cached the students collection in the mongoDbObj object to avoid calling collections() over and over. Following statement fetches all students from the database:

mongoDbObj.students.find().toArray(function(err, data){
  if(err){
    console.log(err);
  else{
    //operate with the deta
  }
});


The find() method returns the objects in the form of documents. We need to convert the data obtained to a JavaScript array to operate with it easily. This is done by the toArray method.

Following are some examples showing using find with conditions:

mongoDbObj.students.find({studentId:1})    //Fetches the student with value of studentId 1
mongoDbObj.students.find({studentId:{$gte:2}})    //Fetches the student with value of studentId greater than or equal to 2
mongoDbObj.students.find({"marks.totalMarks":500})    //Fetches the student with at least one of the values of totalMarks 500
mongoDbObj.students.find({"marks.totalMarks":{$lte:500}})    //Fetches the student with at least one of the values of totalMarks less than or equal to 500


Inserting data:

Inserting data is a straight forward operation. It needs the object to be inserted, an optional options object and a callback to handle the success or failure.


mongoDbObj.students.insert(newStudent,{w:1},function(err, result){
  if(err){
    //Handle the failure case
  }
  else{
    //Handle the success case 
  }
});


The value of options object passed in above call to insert method is used to get acknowledgement of write operations.

Updating data:

Following statement replaces the matched object:

mongoDbObj.students.update({studentId:1},{name:”Ravi Kiran”},{w:1}, function(err, result){
    //Handle success and failure
});


The issue with the above approach is, as it does a full replace, there is a possibility of losing data of other fields in the matched record. Following statement updates the specified fields leaving unspecified fields untouched:

mongoDbObj.students.update({studentId:1},{$set: {name:”Ravi Kiran”}},{w:1}, function(err, result){
  //Handle success and failure
});


Deleting data:

Calling remove() method without any conditions deletes all records in a collection:


mongoDbObj.students.remove(function(err, result){
    //Handle success and failure
});


If a condition is passed in, it deletes the records that match the criteria:

mongoDbObj.students.remove({studentId:studentId},{w:1},function(err, result){
    //Handle success and failure
});
We will discuss more about MongoDB and Node.js in future posts.

Happy Coding!

Sunday, 8 June 2014

Expanding my Writing Zone

I started this blog as a novice blogger less than 2 years back and I had an amazing writing experience till now. I just can’t say enough about the accolades I received from the readers of this blog and also some constructive criticism that helped me in writing better. Thanks to each one of you that are reading this blog. I will continue writing good content here. In addition to writing for my blog, I started writing content for two of leading content publishers on the internet.

DotNet Curry Magazine:
DotNet Curry Magazine (DNC Magazine) is a free magazine for .NET developers around the world. It is started and ran by a set of technology experts including Suprotim Agarwal, a Microsoft MVP for ASP.NET/IIS. Suprotim is the Editor-in-chief for the magazine. The magazine releases an issue on every alternate month with high quality content on latest Microsoft Technologies. I am one of the thousands of subscribers to the magazine and I highly recommend subscribing to the magazine. The authors are MVPs and experts around the world. I am fortunate to have joined the team of authors. My first article for DNC was published during the May 2014 edition of the magazine and the article is now available on their website too, you can check it here. Stay tuned for lots of .NET content on DNC Magazine from all the authors.


Check my author page on DotNetCurry site: http://www.dotnetcurry.com/author.aspx?AuthorName=Ravi%20Kiran

Site Point:
Sitepoint is a very well-known site for many developers as a source of knowledge on several topics including HTML, CSS, JavaScript, Mobile, UX, Design and other topics. They publish articles, books, courses and also have forums for Q&A. I read several of their articles focussed on front-end web technologies. I contacted Sitepoint to know I could write for them and the editor-in-chief Ophelie Lechat accepted me as an author for their site. As most of you would have already guessed, I will be posting articles focused on JavaScript for Sitepoint. My first article for Sitepoint is published, you can read it here. Also check articles by other authors, they will help you for sure. I have a nice set of articles planned to be published for Sitepoint. Follow their twitter feed for tweets on their articles and also for technology news.

Check my author page on SitePoint: http://www.sitepoint.com/author/rkiran/

I was busy in initiating my work for these writing assignments and writing articles. So, I couldn't get enough time to blog. But, I have a nice series planned for this blog and you will see the posts popping up soon.

Happy coding!

Thursday, 8 May 2014

Building a Todo list application using Node.js and Express.js on Visual Studio

Some of you might have surprised to see the title containing Node, Express and Visual Studio together. Yes, it is possible to build Node.js applications on Visual Studio. In case, if you don’t know Visual Studio also has an extension for developing Python applications, you need to install the PTVS (Python Tools for Visual Studio) to be able to do it. The team that developed on PTVS also developed NTVS (Node.js Tools for Visual Studio) with help from a couple of community folks. NTVS is open source right from the beginning and accepts community contributions. The project is still in beta, so it has some pain points, but still it works pretty well. To follow along with this post, download and install the extension from its codeplex site. It works with the 2012 and 2013 versions of Visual Studio.

After installing NTVS, fire up Visual Studio and choose File -> New -> Project. In the dialog, expand Other Languages, and the node JavaScript under that. You will see a new option Node.js added here. Under this, you will find a number of project templates to start developing Node.js applications.


If you have TypeScript installed, you will find the same set of templates under TypeScript node as well.

Let us start building a simple Todo list application using NTVS. From the new project dialog, select Blank Express Application, change name of the application to Express-Todo and hit OK.

The new project we just created has all the set up ready for developing a Node – Express application. The project has the following NPM packages installed; you can find them under the npm node in Solution Explorer.


Express is a light weight server framework to develop Node.js applications. Jade is the most popular view engine used with express to compose the pages. Stylus defines a way to write CSS, takes many pain points of writing CSS away.

The app.js file generated with the project template has a number of middle-wares invoked for us to set up the node application.


app.set('port', process.env.PORT || 3000);  //Port number configured for the application
app.set('views', path.join(__dirname, 'views'));  //Folder under which the view files are stored
app.set('view engine', 'jade');  //Configuring view engine so that express parses them before rendering
app.use(express.favicon());  //Invoking favicon on startup
app.use(express.logger('dev')); 
app.use(express.json());
app.use(express.urlencoded());
app.use(express.methodOverride());
app.use(app.router);
app.use(require('stylus').middleware(path.join(__dirname, 'public')));  //Stylus middleware invocation
app.use(express.static(path.join(__dirname, 'public')));  //Defining relative path for static files


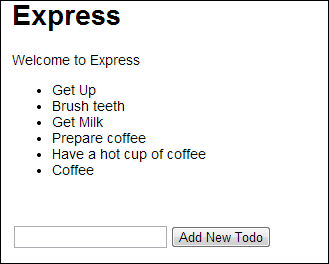
Now run the application. You should be able to see a simple hello World kind of view in the browser.

We need another NPM package, underscore.js. It can be installed in two ways. One is using the dialog offered by NTVS or using npm command on the command prompt. Let us use the GUI dialog to install the package. Right click on the NPM node and choose “Manage npm Modules…”. Go to the tab “Search npm Repository” and type underscore. Choose the package highlighted in the screenshot and hit Install Locally. This step adds the package to the project and adds an entry of underscore to package.json as well.


Check the contents under npm node, you should be able to see the package underscore there.

Add a new JavaScript file to the folder routes and name it todos.js. This file will contain the API service to display and add todo items against an in-memory collection. Following is the code in the file:


var _ = require('underscore');

var listItems =
[
    {
        "id": 1,
        "text": "Get Up"
    },
    {
        "id": 2,
        "text": "Brush teeth"
    },
    {
        "id": 3,
        "text": "Get Milk"
    },
    {
        "id": 4,
        "text": "Prepare coffee"
    },
    {
        "id": 5,
        "text": "Have a hot cup of coffee"
    }
];

exports.list = function(req, res){    
    res.send(listItems);
};

exports.addToList = function (req, res) {
    var maxId = _.max(listItems, function (item) { return item.id });
    console.log(maxId);
    var newTodoItem = { "id": maxId.id + 1, "text": req.body.text };
    listItems.push(newTodoItem);
    res.send({ success: true, item: newTodoItem });
};


I used underscore to calculate the next ID of the todo item. To use underscore, we need to add the require declaration at the beginning of the file, it is similar to the using statements in C# code files. All members to be exposed to the outside world have to be added to the exports object.

In order to expose the above methods as APIs, we need to define the HTTP method and attach a route path to them. In the app.js file add the following statement at the top:

var todos = require('./routes/todos');


This statement brings the module object exposed by the todos.js file. Now all we need to do is define routes, they are done as follows:


app.get('/api/todos', todos.list);
app.post('/api/todos', todos.addToList);


That’s pretty easy, isn’t it? With this, we are done with the work on the server side. Let’s define the components on the client side. As first thing, let’s add jQuery to the layout page. You can install the package using bower and use it or you can point to a CDN as well. Let’s use Google’s CDN path to refer jQuery. Following is the jade tag that does this:


script(src="http://ajax.googleapis.com/ajax/libs/jquery/2.1.0/jquery.min.js")


Now, let’s update the index.jade file to contain the list items. Following is the mark-up of the modified index.jade file:

extends layout

block content
  h1= title
  p Welcome to #{title}
  ul(id="todoList")
  br
  br
  input(type="text" id="txtNewTodo")
  button(id="btnAddTodo") Add New Todo
  script(src="/javascripts/todoOperations.js")


As you see, in jade, one doesn’t require angle brackets to define the tags. It understands nesting through indentation. For indenting the tags, one can use either spaces or tabs; but not both. We are yet to define the todoOperations.js file referred above. Let’s do it now. Add a JavaScript file to the javascripts folder under public folder and name it todoOperations.js. Code in this file is pretty straight forward, if you know jQuery.

var todoOperations = function () {
    var todos;

    function getAllTodos() {
        //var deferred=$.defer();

        return $.get("/api/todos", function (data) {
            todos = data;
        });
    }

    function addTodo(todoItem) {
        return $.post('/api/todos', todoItem);
    }

    return {
        getAllTodos: getAllTodos,
        addTodo: addTodo
    }
}();

var list;

function refreshTodos() {
    todoOperations.getAllTodos().then(function (data) {
        $.each(data, function () {
            list.append("<li data-id='" + this.id + "'>" + this.text + "</li>");
        });
    });
}

$(function () {
    list = $("#todoList");

    $("#btnAddTodo").click(function () {
        var textBox = $("#txtNewTodo");
        if (textBox.val() !== "") {
            todoOperations.addTodo({ "text": textBox.val() }).then(function (data) {
                if (data.success === true) {
                    list.append("<li data-id='" + data.item.id + "'>" + data.item.text + "</li>");
                    textBox.val('');
                }
            });
        }
    });

    refreshTodos();
});


Now run the application. You will be able to see the list of todo items populated on the page and you will also be able to add new todo items. 
 
To update and delete the todo items, you need to define the methods in the todos,js file and add routes for them in the app.js file using app.put and app.delete methods. I am leaving it as an exercise for you :)

Happy coding!

Thursday, 17 April 2014

$parsers and $formatters in Custom Validation Directives in Angular JS

While writing applications using Angular JS, sometimes we need to define our own validators. Custom validations in Angular JS are created as directives with a dependency on the ng-model directive. At times, key part of the validation depends on controller of the ng-model directive.

The ng-model directive provides two arrays of functions to which the custom validation logic can be hooked: $parsers and $formatters. Usage of both of these arrays looks similar, but they are invoked under different conditions.

$parsers:
In most of the cases, $parsers is the right option to handle the logic of custom validation. Functions added to $parsers are called as soon as the value in the form input is modified by the user. As an example, consider the following directive:


app.directive('evenNumber', function(){
  return{
    require:'ngModel',
    link: function(scope, elem, attrs, ctrl){
      ctrl.$parsers.unshift(checkForEven);
      
      function checkForEven(viewValue){
        if (parseInt(viewValue)%2 === 0) {
          ctrl.$setValidity('evenNumber',true);
        }
        else{
          ctrl.$setValidity('evenNumber', false);
        }
        return viewValue;
      }
    }
  };
  
});


This is a simple directive that checks if the number entered in the textbox is even. If we apply validation on a textbox, the validator works as long as the value is modified in the textbox.

$formatters:
Formatters are invoked when the model is modified in the code. They are not invoked if the value is modified in the textbox. $formatters are useful when there is a possibility of the value getting modified from the code. $formatters can be applied in the above directive using a simple statement:


ctrl.$formatters.unshift(checkForEven);


Now, the validation on the textbox containing the evenNumber is fired when the value is directly modified or even when the value is modified in the code.

A demo of the directive is available on plnkr.

Happy coding!

Sunday, 30 March 2014

Basics: Benefits of Writing Unit Tests

Quite often people ask the reasons of writing unit tests for their code. There are several benefits of writing unit tests that add value to the code as well as the developers writing the tests. I am listing a set of points here that came to my mind while thinking about the benefits of Unit testing.

Benefits to code:
  • The code will have very few bugs as most of them are identified and resolved while running tests
  • Silly mistakes are inevitable while writing code. Identifying them while running the application is difficult at times. Unit tests catch them instantly
  • Code doesn’t need documentation. Names of the behaviours or methods defined in unit tests shout the purpose of their part
  • Testable code is easily extensible too. Adding new features to the code becomes easy
  • If Unit tests are written right from beginning of development, the underlying code automatically follows a set of quality measures that are otherwise very difficult to achieve
  • After applying some modifications, the code can be shipped within very less amount of time, as most of the regression testing is also done by the unit tests


Benefits to Programmers:
  • Unit testing teaches good programing practices to developers
  • Unit tests force programmers to use some of the features of the language and framework that would otherwise remain just as theories in programmers’ minds
  • As we write more code, our thinking about code starts maturing. With unit tests, we are bound to write a lot of additional code than the usual production code. So, it improves the programmer’s ability to think logically
  • Programmers gain the experience of writing clean, loosely coupled code and learn the ways to avoid anti-patterns
  • It becomes very easy for any new member to understand and start working on the code


These are just my opinions. The list is definitely not limited to the above set of points. Feel free to put a comment on anything that I didn’t mention in the above list.

Happy coding!

Sunday, 9 March 2014

A Closer Look at the Identity Client Implementation in SPA Template

Sometime back, we took a look at the identity system in ASP.NET and its support for both local and remote accounts. In this post, we will take a closer look at the way it is used in the Single Page Application template that comes with Visual Studio 2013.

The SPA application is a JavaScript client that uses an authenticated Web API. The Web API exposes a number of API methods to manage users. The JavaScript code uses jQuery for AJAX and Knockout for data binding has a number of methods that accomplish the task of managing the user. Let’s take a look at how the local users are authenticated.

Identity Client Implementation for Local Users:
If you check the Web API’s authentication configuration class, it exposes an endpoint at /Token for serving authorization token. Login credentials of the user have to be posted to this URL to get the user logged in. In response, the endpoint sends some data of which access token is a component. The access token has to be saved and used for subsequent requests to indicate the session of the logged in user.

Following code in the app.datamodel.js file sends a post request to the ‘/Token’ endpoint to login the user:


self.login = function (data) {
    return $.ajax(loginUrl, {
        type: "POST",
        data: data
    });
};

Following is the snippet from login.viewmodel.js that calls the above method:
dataModel.login({
    grant_type: "password",
    username: self.userName(),
    password: self.password()
}).done(function (data) {
    self.loggingIn(false);

    if (data.userName && data.access_token) {
        app.navigateToLoggedIn(data.userName, data.access_token, self.rememberMe());
    } else {
        self.errors.push("An unknown error occurred.");
    }
});


There are a couple of things to be noticed in the above code:

  • The property grant_type has to be set in the data passed to the login method
  • The navigateToLoggedIn method stores the access token in browser’s local storage to make it available for later use

To sign up for a new user, we just need to post the user’s data to the endpoint at ”/api/Account/Register”. Once the user is successfully registered, it sends a login request to the token endpoint discussed above to login the user immediately. Code for this can be found in the register method of register.viewmodel.js file. Following is the snippet that deals with registering and logging in:


dataModel.register({
    userName: self.userName(),
    password: self.password(),
    confirmPassword: self.confirmPassword()
}).done(function (data) {
    dataModel.login({
        grant_type: "password",
        username: self.userName(),
        password: self.password()
    })
    ......


Identity Client Implementation for External Login Users:
Identity implementation for external accounts is a bit tricky; because it involves moving the scope to a public web site and a number of API calls. When the application loads, it gets the list of external login providers by sending an HTTP GET request to “/api/Account/ExternalLogins”. Following method in app.datamodel.js does this:


self.getExternalLogins = function (returnUrl, generateState) {
    return $.ajax(externalLoginsUrl(returnUrl, generateState), {
        cache: false,
        headers: getSecurityHeaders()
    });
};

The parameter returnUrl used in the above method is where the user would be redirected after logging in from the external site.

Based on the providers obtained from the server, the provider specific login buttons are shown on the page. When a user chooses to use an external login provider, the system redirects him to the login page of the chosen provider. Before redirecting, the script saves the state and the URL redirected in session storage and local storage (both are used to make it work on most of the browsers). This information will be used once the user comes back to the site after logging in. Following snippet in login.viewmodel.js does this:


self.login = function () {
    sessionStorage["state"] = data.state;
    sessionStorage["loginUrl"] = data.url;
    // IE doesn't reliably persist sessionStorage when navigating to another URL. Move sessionStorage temporarily
    // to localStorage to work around this problem.
    app.archiveSessionStorageToLocalStorage();
    window.location = data.url;
};


Once the user is successfully authenticated by the external provider, the external provider redirects the user to the return URL with an authorization token in the query string. This token is unique for every user and the provider. This token is used to check if the user has already been registered to the site. If not, he would be asked to do so. Take a look at the following snippet from the initialize method in app.viewmodel.js:
......       
 } else if (typeof (fragment.access_token) !== "undefined") {
    cleanUpLocation();
    dataModel.getUserInfo(fragment.access_token)
    .done(function (data) {
    if (typeof (data.userName) !== "undefined" && typeof (data.hasRegistered) !== "undefined"
            && typeof (data.loginProvider) !== "undefined") {
        if (data.hasRegistered) {
            self.navigateToLoggedIn(data.userName, fragment.access_token, false);
        }
        else if (typeof (sessionStorage["loginUrl"]) !== "undefined") {
            loginUrl = sessionStorage["loginUrl"];
            sessionStorage.removeItem("loginUrl");
            self.navigateToRegisterExternal(data.userName, data.loginProvider, fragment.access_token,                              loginUrl, fragment.state);
        }
        else {
            self.navigateToLogin();
        }
    } else {
        self.navigateToLogin();
    }
})
......


It does the following:

  • Clears the access token from the URL
  • Queries the endpoint ‘/api/UserInfo’ with the access token for information about the user
  • If the user is found in the database, it navigates to the authorized content
  • Otherwise, navigates to the external user registration screen, where it asks for a local name

The external register page accepts a name of user’s choice and posts it to ‘/api/RegisterExternal’. After saving the user data, the system redirects the user to login page with value of state set in the session and local storages and also sends the authorization token with the URL. The login page uses this authorization token to identify the user.


dataModel.registerExternal(self.externalAccessToken, {
        userName: self.userName()
    }).done(function (data) {
        sessionStorage["state"] = self.state;
        // IE doesn't reliably persist sessionStorage when navigating to another URL. Move sessionStorage
        // temporarily to localStorage to work around this problem.
        app.archiveSessionStorageToLocalStorage();
        window.location = self.loginUrl;
    })


For logout, an HTTP POST request is sent to ‘/api/Logout’. It revokes the claims identity that was associated with the user. The client code removes entry of the access token stored in the local storage.

Happy coding!

Monday, 17 February 2014

Consuming ASP.NET Web API OData Batch Update From JavaScript

Consuming OData with plain JavaScript is a bit painful, as we would require handling some of the low-level conversions. datajs is a JavaScript library that simplifies this task.

datajs converts data of any format that it receives from the server to an easily readable format. The batch request sent is a POST request to the path /odata/$batch, which is made available if batch update option is enabled in the OData route configuration.

As seen in the last post, a batch update request bundles of a number of create put and patch requests. These operations have to be specified in an object literal. Following snippet demonstrates it with a create, an update and a patch request:


var requestData = {
    __batchRequests: [{
        __changeRequests: [
            {
                requestUri: "/odata/Customers(1)",
                method: "PATCH",
                data: {
                    Name: "S Ravi Kiran"
                }
            },
            {
                requestUri: "/odata/Customers(2)"
                data: {
                    Name: "Alex Moore",
                    Department: "Marketing",
                    City:"Atlanta"
                }
            },
            {
                requestUri: "/odata/Customers",
                method: "POST",
                data: {
                    Name: "Henry",
                    Department: "IT",
                    City: "Las Vegas"
                }
            }
        ]
    }]
};

Following snippet posts the above data to the /odata/$batch endpoint and then extracts the status of response of each request:

OData.request({
    requestUri: "/odata/$batch",
    method: "POST",
    data: requestData,
    headers: { "Accept": "application/atom+xml"}
}, function (data) {
    for (var i = 0; i < data.__batchResponses.length; i++) {
        var batchResponse = data.__batchResponses[i];
        for (var j = 0; j < batchResponse.__changeResponses.length; j++) {
            var changeResponse = batchResponse.__changeResponses[j];
        }
    }
    alert(window.JSON.stringify(data));
}, function (error) {
    alert(error.message);
}, OData.batchHandler);


Happy coding!